The team is working hard. The sprint board keeps moving. Yet the date promised to a customer moves again. Before asking for more accurate estimates, find out what happens between “development complete” and “available to users.”
A delivery date includes more than coding time. A change may wait for review, a shared test environment, a decision, a deployment window or activation for the intended customer. If those waits are invisible, adding precision to the development estimate leaves the rest of the journey unexplained.
Define what “done” means for this decision
Start with the commitment that matters. Is the customer waiting for a demonstration, a healthy production deployment or access to a specific feature? These are different endpoints. A successful pipeline does not, by itself, establish that the intended users can use the change.
Choose a start and an end before measuring. For a release already prepared, that might be “release candidate ready” to “available to the intended users.” For developer feedback, it could be “change submitted” to “first actionable result.” Do not combine those journeys into a single number and expect it to explain both.
Trace a real change before redesigning the process
Select a recent change and reconstruct its actual route. Record when it became ready for each step, when work began, when it ended and why it returned to an earlier step. Link the change to its build artifact, deployment and activation where those records exist.
- Active work: review, testing, investigation and deployment execution.
- Waiting: an item is ready, but a person, environment or decision is unavailable.
- Rework: a failed check or changed requirement sends the item back.
- Intentional delay: a commercial release date or required approval deliberately holds the change.
Keep missing evidence visible. An undocumented interval is a question to investigate, not proof that a particular team caused a delay.
The longest task is not automatically the constraint
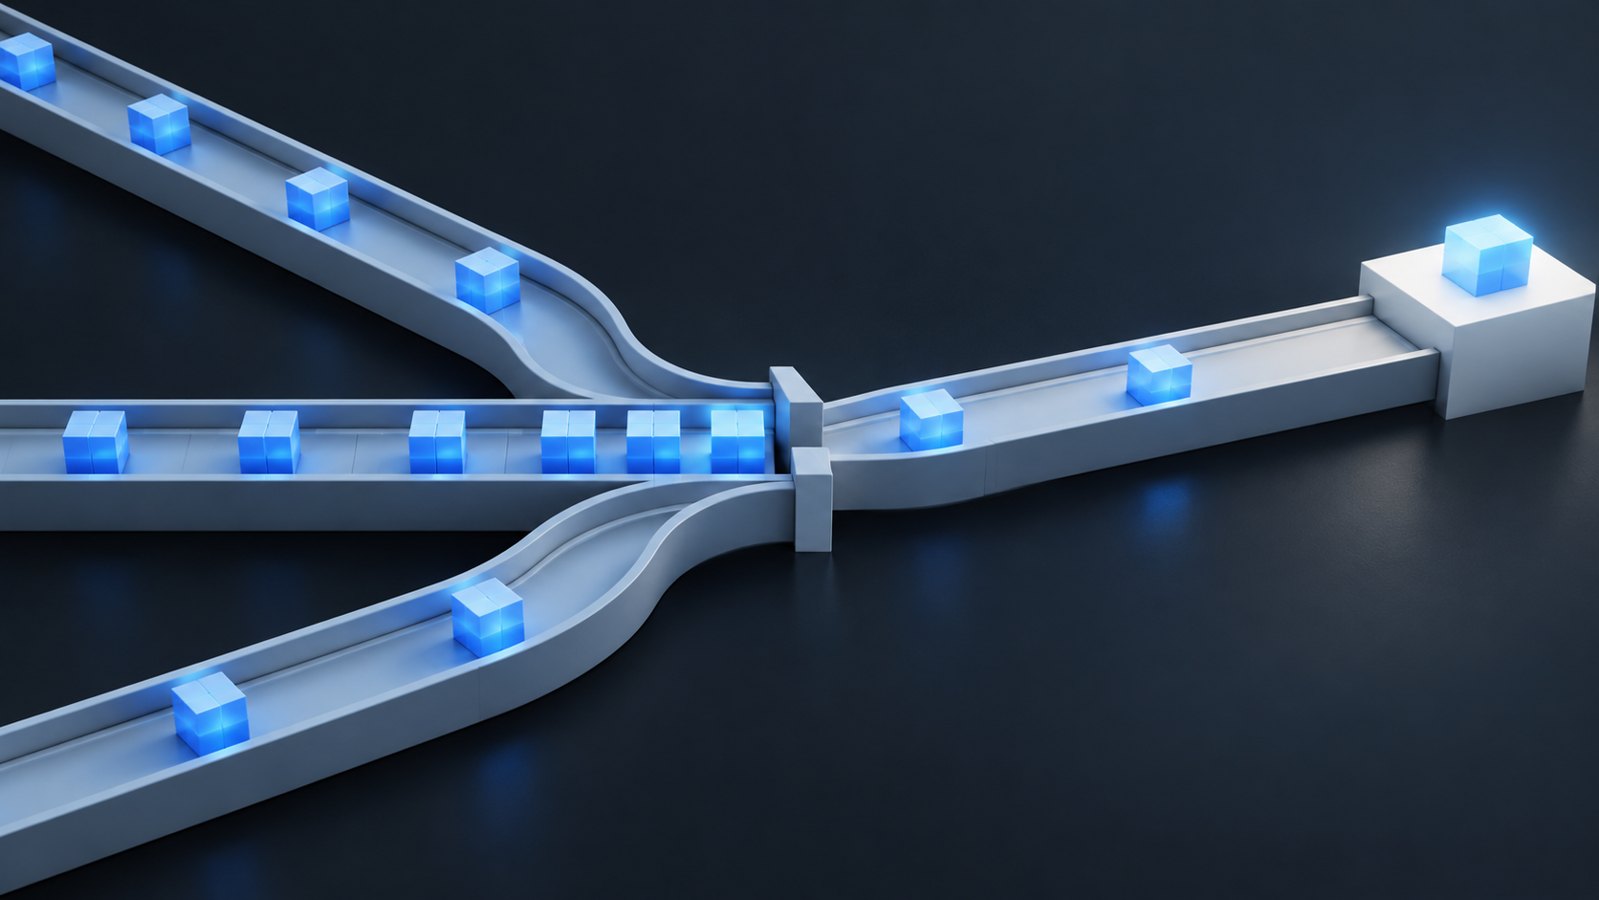
Consider an illustrative release: two required validation branches begin together. One completes after 30 minutes; the other takes 40. The join completes after 40 minutes, assuming nothing else is required. The elapsed time is not 70 minutes. Shortening the first branch alone does not bring that join forward.
A single execution also does not establish a recurring capacity constraint. Look across comparable changes for repeated queues, growing item age, arrivals versus completions and the reasons work is blocked. Separate release routes if their dependencies differ.
Choose an intervention that tests an explanation
“Improve delivery” is too broad to evaluate. A more useful intervention names the suspected delay, a responsible owner, a bounded change and the evidence that would support keeping it.
For example, if completed reviews repeatedly wait for a shared validation slot, test a smaller admission batch or a different slot policy on a defined route. If review waits dominate, examine review ownership and work in progress. Neither finding automatically justifies replacing the CI platform.
Compare the same endpoint before and after. Also check reliability, rework and recovery: moving a release earlier while creating more failures may simply move the cost downstream.
Use the evidence to make the next commitment
A practical GamePlan connects the observed problem to priorities, owners and a next experiment. It should distinguish what is known, what remains a hypothesis and which decision the next measurement will enable.
The first useful outcome may be a clearer commitment: what can be delivered, which dependencies still matter and when the forecast will be revisited. That gives a founder or engineering leader a better basis for talking to a customer than another unexplained date.
Explore Delivery Predictability to see how Axelerant approaches recurring delivery delays, or discuss the situation your team is facing.
